Resume template · Updated October 2026
Data engineer resume template
Short answer
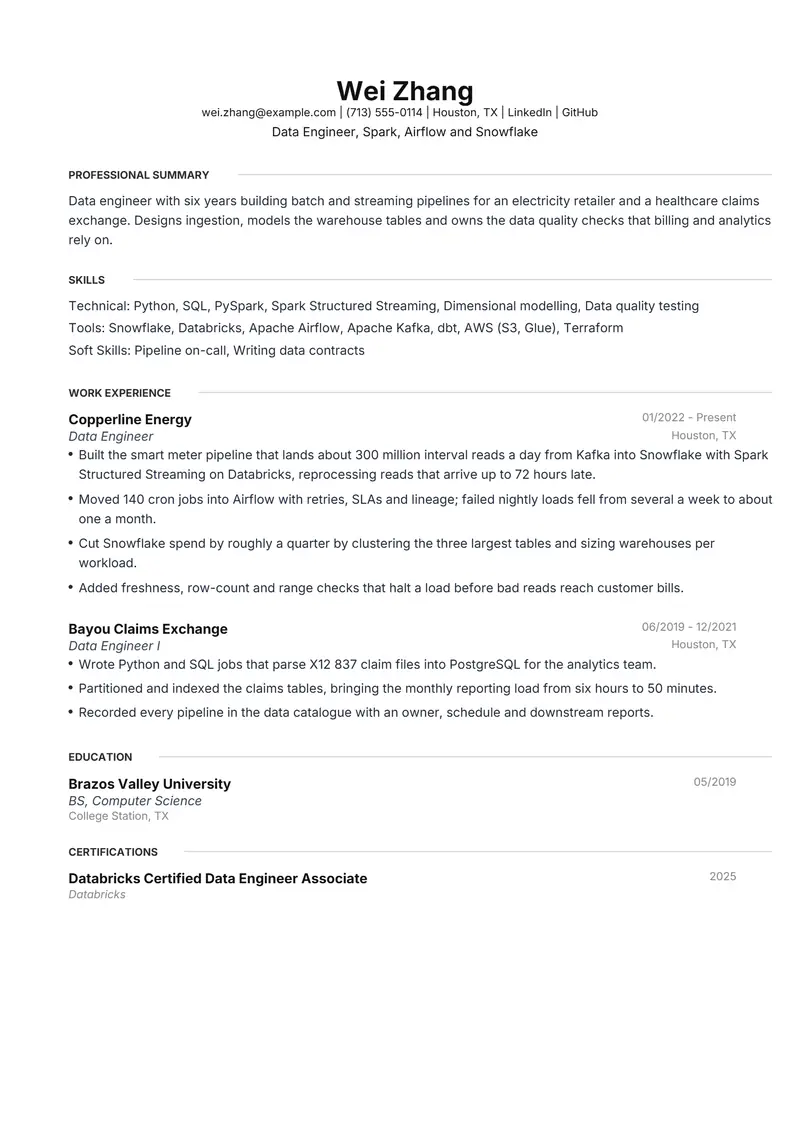
Meridian is a good fit for data engineers, whose interviews often begin with the stack: it prints Spark, Airflow, Kafka and Snowflake in labelled rows above the first job. The fictional sample spent six years on pipelines for an electricity retailer and a healthcare claims exchange, with bullets on daily volumes, late-arriving data, failed loads, warehouse cost and quality checks that stop bad data reaching billing.
Download the data engineer sample
Wei is a fictional data engineer. Replace every detail with your own before you send it.
The files are made in your browser by Resumity's own exporters, from this sample. The builder opens it as your own resume: click any line to replace it. Free plan, no watermark.
Why Meridian suits a data engineer resume
Meridian sits skills above work experience, which helps most when the tools are a large part of the job, and for data engineers they are: postings filter on Spark, Airflow, dbt, a warehouse and a cloud by name. The labelled rows make the match visible before the reader starts on the bullets, on a plain page with no colour.
Second choice: Catalyst. Catalyst drops the summary and opens on the latest job; switch to it once you are senior and one platform you built makes the whole case.
What goes in each section, in Meridian's order
Meridian prints its sections in a fixed order, the same in the PDF and the Word file. Here is that order for this sample, and what to put in each section.
- Professional Summary. Two sentences: batch, streaming or both; the kind of data (meter reads, claims, events, transactions); and what you own beyond the pipeline itself, such as warehouse models or data quality. Downstream teams named here (billing, analytics, ML) tell a reader how critical your data is.
- Skills. Technical for languages and concepts (Python, SQL, PySpark, data modelling, streaming); Tools for the platforms (warehouse, orchestrator, lakehouse, cloud services, infrastructure as code). Name the exact product: "Airflow" and "Snowflake" are searched for, "orchestration" and "cloud warehouse" are not.
- Work Experience. Give each pipeline a volume and a freshness: rows or events per day, how late data can arrive, how fast it lands. Then add a reliability bullet (failed loads, SLAs, retries), a cost bullet and one on data quality checks. Those four are what data platform leads screen for.
- Education. Degree and year on one line. Computer science, information systems, maths or an engineering field are all common; a bootcamp can sit here if it is your main training.
- Certifications. Meridian prints certifications last. A platform credential such as Databricks Certified Data Engineer Associate helps if you use that platform; Databricks lists it as valid for two years, so keep the year visible.
The sample resume as text
The same content as the files above, so you can copy a line or compare it with your own.
Wei Zhang
Data Engineer, Spark, Airflow and Snowflake
Houston, TX | wei.zhang@example.com | (713) 555-0114 | linkedin.com/in/sample-wei-zhang | github.com/sample-wei-zhang
Data engineer with six years building batch and streaming pipelines for an electricity retailer and a healthcare claims exchange. Designs ingestion, models the warehouse tables and owns the data quality checks that billing and analytics rely on.
Experience
Data Engineer, Copperline Energy, Houston, TX (01/2022 to Present)
- Built the smart meter pipeline that lands about 300 million interval reads a day from Kafka into Snowflake with Spark Structured Streaming on Databricks, reprocessing reads that arrive up to 72 hours late.
- Moved 140 cron jobs into Airflow with retries, SLAs and lineage; failed nightly loads fell from several a week to about one a month.
- Cut Snowflake spend by roughly a quarter by clustering the three largest tables and sizing warehouses per workload.
- Added freshness, row-count and range checks that halt a load before bad reads reach customer bills.
Data Engineer I, Bayou Claims Exchange, Houston, TX (06/2019 to 12/2021)
- Wrote Python and SQL jobs that parse X12 837 claim files into PostgreSQL for the analytics team.
- Partitioned and indexed the claims tables, bringing the monthly reporting load from six hours to 50 minutes.
- Recorded every pipeline in the data catalogue with an owner, schedule and downstream reports.
Education
BS, Computer Science, Brazos Valley University (05/2019)
Certifications
- Databricks Certified Data Engineer Associate, Databricks (2025)
Skills
Python, SQL, PySpark, Spark Structured Streaming, Dimensional modelling, Data quality testing, Snowflake, Databricks, Apache Airflow, Apache Kafka, dbt, AWS (S3, Glue), Terraform, Pipeline on-call, Writing data contracts
How to make the sample yours
Replace the volumes with your own
The sample quotes about 300 million meter reads a day. Use your real order of magnitude in rows, events or terabytes; it is how a reader judges whether your experience matches their scale.
Be honest about "real-time"
If your pipeline lands data every 15 minutes, say so. Interviewers ask about latency, and "near real-time" for an hourly batch job loses trust fast.
Show failures going down
Moving jobs to an orchestrator, adding retries and alerts, writing a backfill process: express the result as failures per month or hours of downtime avoided.
Keep one cost bullet
Warehouse and cluster bills are a growing part of data engineering. Clustering, partitioning, right-sizing compute or dropping unused tables all count; give a rough share saved.
Name the people downstream
Billing, finance close, an ML team or customer-facing reports. When bad data has a visible victim, the quality checks you built read as protection rather than overhead.
Keywords to keep where they are true
Terms this kind of resume is usually searched for. Use the posting's exact wording, and only for work you have done.
- data engineering
- ETL and ELT
- data pipelines
- Apache Spark
- PySpark
- Apache Airflow
- Apache Kafka
- Snowflake
- Databricks
- dbt
- data modelling
- data quality
- streaming
- AWS
- Terraform
Mistakes to avoid
- A long tool list with no volumes, latencies or consumers anywhere on the page.
- Calling hourly or daily batch jobs "real-time".
- Leaving out failures and backfills. Every pipeline breaks; how you handled it is the evidence.
- Describing dashboards or ad-hoc SQL as data engineering when the role asks for pipelines.
How the sample PDF reads in text extractors
We exported this sample with Resumity's PDF exporter in Chrome on 2026-10-29 and read the file back with three open-source text extractors. This shows whether software that turns a PDF into text can recover it; it is not a test of any commercial applicant tracking system. How we test templates.
| Extractor | Name, email, phone | Headings | Bullets intact |
|---|---|---|---|
| pdf.js 4.10.38 | All found | 5 of 5 | 7 of 7 |
| pdftotext (Xpdf) 4.00 | All found | 5 of 5 | 7 of 7 |
| pypdf 6.13.0 | All found | 5 of 5 | 7 of 7 |
Frequently asked questions
Do data engineers need a certification?
No, but a platform credential can help when you are new to that platform or switching from analytics. Databricks lists its Data Engineer Associate as valid for two years, after which you recertify.
How do I show scale without revealing confidential figures?
Give orders of magnitude (hundreds of millions of rows a day, tens of terabytes) or relative changes. Those show the size of the problem without exposing business numbers.
Should SQL go on the resume even though every data engineer knows it?
Yes. It is searched for by name, and specifics such as window functions, incremental models or query tuning show depth beyond basic selects.
I am moving from data analyst to data engineer. What changes on the page?
Lead with any pipeline, scheduling or modelling work you have done, even inside an analyst role, and move dashboards to a single line. The analytics engineer page is a natural middle step if your work is mostly dbt and SQL.
How do I describe on-call work for pipelines?
Say how often you are on rotation, what kind of incidents you handle (late feeds, failed loads, schema changes upstream) and one fix that stopped an incident from recurring.
Will applicant tracking systems read this Meridian PDF?
The sample PDF read back with its contact details, all 5 section headings and all 7 bullets intact in three open-source text extractors (pdf.js, pdftotext and pypdf). Commercial systems such as Workday, Greenhouse or Taleo were not tested, and each employer configures its own.
Guides and templates for this resume
Sources, checked 29 October 2026
We opened every page below on that date. Pay, rules and requirements change, so check the source before you rely on a detail.
- Databricks: Databricks Certified Data Engineer Associate (exact certification name; no prerequisites; validity period 2 years, recertification required)
More in resume templates by job title.