Resume template · Updated October 2026
Site reliability engineer resume template
Short answer
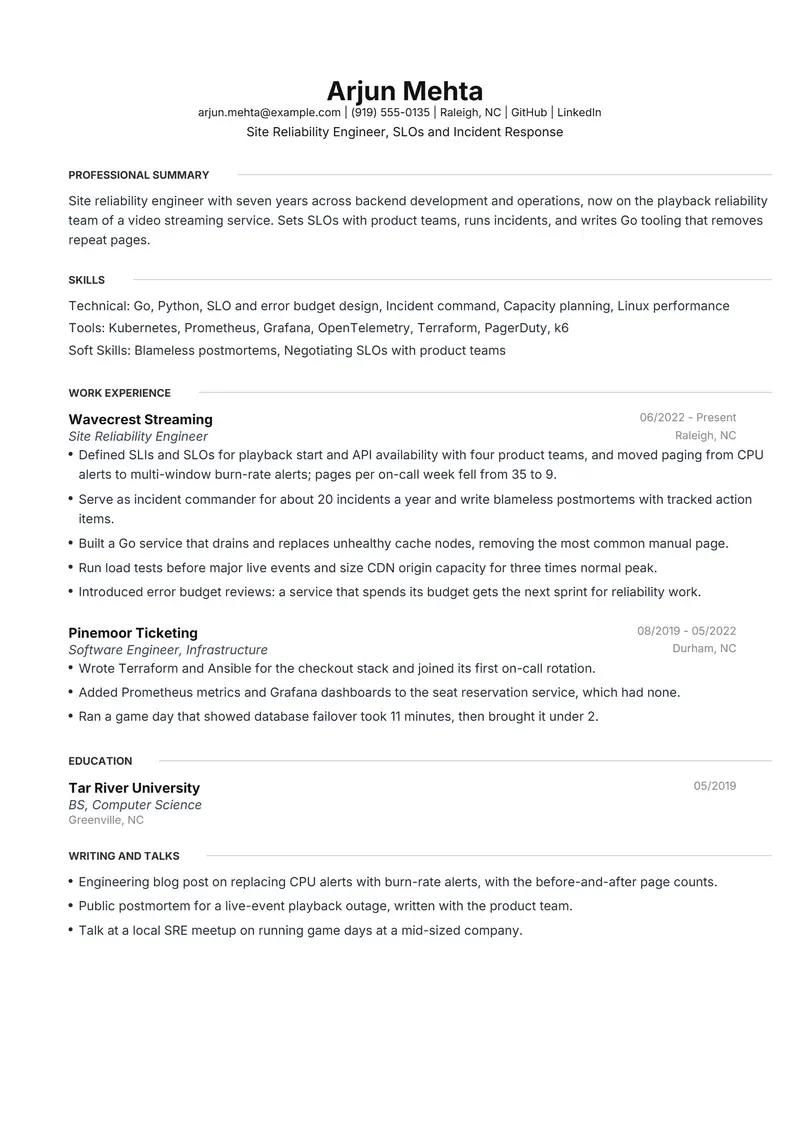
Meridian is a good fit for a site reliability engineer: skills print in labelled rows above the jobs, so a screener sees both the code (Go, Python) and the monitoring and paging stack before the first bullet. The fictional sample moved from backend development into SRE at a video streaming service, with SLOs agreed with product teams, burn-rate alerting, incident command and Go tooling that removes repeat pages.
Download the site reliability engineer sample
Arjun is a fictional site reliability engineer. Replace every detail with your own before you send it.
The files are made in your browser by Resumity's own exporters, from this sample. The builder opens it as your own resume: click any line to replace it. Free plan, no watermark.
Why Meridian suits a site reliability engineer resume
Meridian lists skills above experience and uses grey rules with no colour. An SRE screen checks two things quickly, whether you write code and whether you know the observability and incident tooling, and Meridian answers both in the top third of the page; its plain styling also suits bullets that are dense with numbers.
Second choice: Catalyst. Catalyst drops the summary and opens on your current job with teal headings; choose it if you are senior and the latest reliability role makes the case on its own.
What goes in each section, in Meridian's order
Meridian prints its sections in a fixed order, the same in the PDF and the Word file. Here is that order for this sample, and what to put in each section.
- Professional Summary. Say how your time splits between code and operations and what you are on call for. "Sets SLOs with product teams" tells a reader you practise SRE as a discipline, not as a new name for an operations desk.
- Skills. Put programming languages first in Technical, since many SRE loops include a coding round, followed by practices such as SLO design, incident command and capacity planning. Tools holds monitoring, tracing, paging and load testing, each by its product name.
- Work Experience. Use reliability numbers: SLO targets, pages per on-call week, time to detect and to recover, toil removed. The Google SRE book defines an SLO as a target value for a service level measured by an SLI; use the terms in that sense, because an interviewer will probe how you chose each target.
- Education. One line. In SRE hiring the coding and systems rounds weigh far more than the subject of your degree.
- Writing and talks. Meridian prints this list last. The sample calls it "Writing and talks": a public postmortem, a blog post, a meetup talk. Each shows how you explain a failure, which is half of incident work.
The sample resume as text
The same content as the files above, so you can copy a line or compare it with your own.
Arjun Mehta
Site Reliability Engineer, SLOs and Incident Response
Raleigh, NC | arjun.mehta@example.com | (919) 555-0135 | github.com/sample-arjun-mehta | linkedin.com/in/sample-arjun-mehta
Site reliability engineer with seven years across backend development and operations, now on the playback reliability team of a video streaming service. Sets SLOs with product teams, runs incidents, and writes Go tooling that removes repeat pages.
Experience
Site Reliability Engineer, Wavecrest Streaming, Raleigh, NC (06/2022 to Present)
- Defined SLIs and SLOs for playback start and API availability with four product teams, and moved paging from CPU alerts to multi-window burn-rate alerts; pages per on-call week fell from 35 to 9.
- Serve as incident commander for about 20 incidents a year and write blameless postmortems with tracked action items.
- Built a Go service that drains and replaces unhealthy cache nodes, removing the most common manual page.
- Run load tests before major live events and size CDN origin capacity for three times normal peak.
- Introduced error budget reviews: a service that spends its budget gets the next sprint for reliability work.
Software Engineer, Infrastructure, Pinemoor Ticketing, Durham, NC (08/2019 to 05/2022)
- Wrote Terraform and Ansible for the checkout stack and joined its first on-call rotation.
- Added Prometheus metrics and Grafana dashboards to the seat reservation service, which had none.
- Ran a game day that showed database failover took 11 minutes, then brought it under 2.
Writing and talks
- Engineering blog post on replacing CPU alerts with burn-rate alerts, with the before-and-after page counts.
- Public postmortem for a live-event playback outage, written with the product team.
- Talk at a local SRE meetup on running game days at a mid-sized company.
Education
BS, Computer Science, Tar River University (05/2019)
Skills
Go, Python, SLO and error budget design, Incident command, Capacity planning, Linux performance, Kubernetes, Prometheus, Grafana, OpenTelemetry, Terraform, PagerDuty, k6, Blameless postmortems, Negotiating SLOs with product teams
How to make the sample yours
Replace the paging numbers with your own
The sample takes pages per on-call week from 35 to 9. Your paging tool keeps this history, and a before-and-after pair like it is among the strongest lines an SRE can write.
Write each SLO in user terms
State it from the user side, for example "99.9% of playback starts within 2 seconds over 28 days", rather than as a server metric. It shows you chose what to measure.
Show the toil you automated away
The cache-node drain service removed the most common manual page. Name one task you scripted out of existence and roughly how often it used to wake someone.
Tell one incident without drama
Your role (commander, responder, scribe), how long it lasted and what changed afterwards. Keep the language blameless; a bullet that blames a person or a team reads badly to reliability leads.
Keep a coding bullet in every job
A Go service, a Python capacity model, a Kubernetes operator. Without one, the page reads as an operations resume and invites a different interview.
Keywords to keep where they are true
Terms this kind of resume is usually searched for. Use the posting's exact wording, and only for work you have done.
- site reliability engineering
- SLOs and SLIs
- error budgets
- incident response
- incident command
- blameless postmortems
- on-call
- observability
- Prometheus
- Grafana
- OpenTelemetry
- Kubernetes
- capacity planning
- load testing
- toil reduction
Mistakes to avoid
- Uptime figures with no definition of what counted as up or where it was measured.
- Incidents listed without your role in them.
- A page with no programming on it; it reads as an operations resume.
- Error budget talk with no consequence. Say what the team did when the budget ran out.
How the sample PDF reads in text extractors
We exported this sample with Resumity's PDF exporter in Chrome on 2026-10-29 and read the file back with three open-source text extractors. This shows whether software that turns a PDF into text can recover it; it is not a test of any commercial applicant tracking system. How we test templates.
| Extractor | Name, email, phone | Headings | Bullets intact |
|---|---|---|---|
| pdf.js 4.10.38 | All found | 5 of 5 | 8 of 8 |
| pdftotext (Xpdf) 4.00 | All found | 5 of 5 | 8 of 8 |
| pypdf 6.13.0 | All found | 5 of 5 | 8 of 8 |
Frequently asked questions
What is the difference between an SLO and an SLA on a resume?
In the Google SRE book, an SLO is a target for a service level measured by an SLI, and an SLA is a contract with users that carries consequences when its targets are missed. Most SRE work is about SLOs; mention an SLA only if you helped set or report on one.
How do I show on-call experience?
Rotation size, pages per week before and after your changes, and your role during incidents. "Incident commander for about 20 incidents a year" is concrete; "participated in on-call" is not.
Does an SRE resume need coding on it?
Yes. Keep languages first in the skills rows and one tooling bullet per job, because most SRE hiring loops include a coding interview and the page should prepare the reader for it.
Can I move from software engineering into SRE?
Often more easily than from operations alone. Show the production side of your developer work: dashboards you added, an on-call rotation you joined, a failover you tested.
How much incident detail can I share?
Describe the type of failure, its duration and what changed after it. Leave out customer names, internal hostnames and anything your employer has not made public.
Will applicant tracking systems read this Meridian PDF?
The sample PDF read back with its contact details, all 5 section headings and all 8 bullets intact in three open-source text extractors (pdf.js, pdftotext and pypdf). Commercial systems such as Workday, Greenhouse or Taleo were not tested, and each employer configures its own.
Guides and templates for this resume
Sources, checked 29 October 2026
We opened every page below on that date. Pay, rules and requirements change, so check the source before you rely on a detail.
- Google (sre.google): Site Reliability Engineering, chapter 4: Service Level Objectives (defines SLI, SLO (a target value for a service level measured by an SLI) and SLA (a contract with consequences))
More in resume templates by job title.